HiRO-ACEv2 Simulates Extreme Weather at 3 Kilometer Resolution at a Fraction of the Cost
HiRO-ACEv2 produces global 3-kilometer climate data for extreme rain, wind, and pressure at 1/300th of X-SHiELD cost, with models and demos available.

HiRO-ACEv2 produces global 3-kilometer climate data for extreme rain, wind, and pressure at 1/300th of X-SHiELD cost, with models and demos available.
LMCache 0.5.6 fixes a shared cache bug; Kubernetes operators need network controls, rebuilt images, and restarts before production.
Software Engineering CoWork tests coding agents in simulated workplaces; eleven models pass tests but rarely complete tasks, delivery gaps remain.
Jacob Andreas builds AI interpretability tools that make ML models explain their learning, improving accuracy and robustness in high-stakes systems.
RoadMOPD reduces teacher conflicts in multi-teacher distillation, improving student accuracy by up to 8.78 points in medical tests with Qwen3-4B.
Speculative Forcing accelerates autoregressive video generation by freezing tokens that already look settled, avoiding unnecessary final denoising steps. Accepted tokens remain cached as context, so t…
Orbia shifts video generator evaluation from visual appeal to coherent 3D worlds, testing 27 models on input, frame, and spatial consistency.
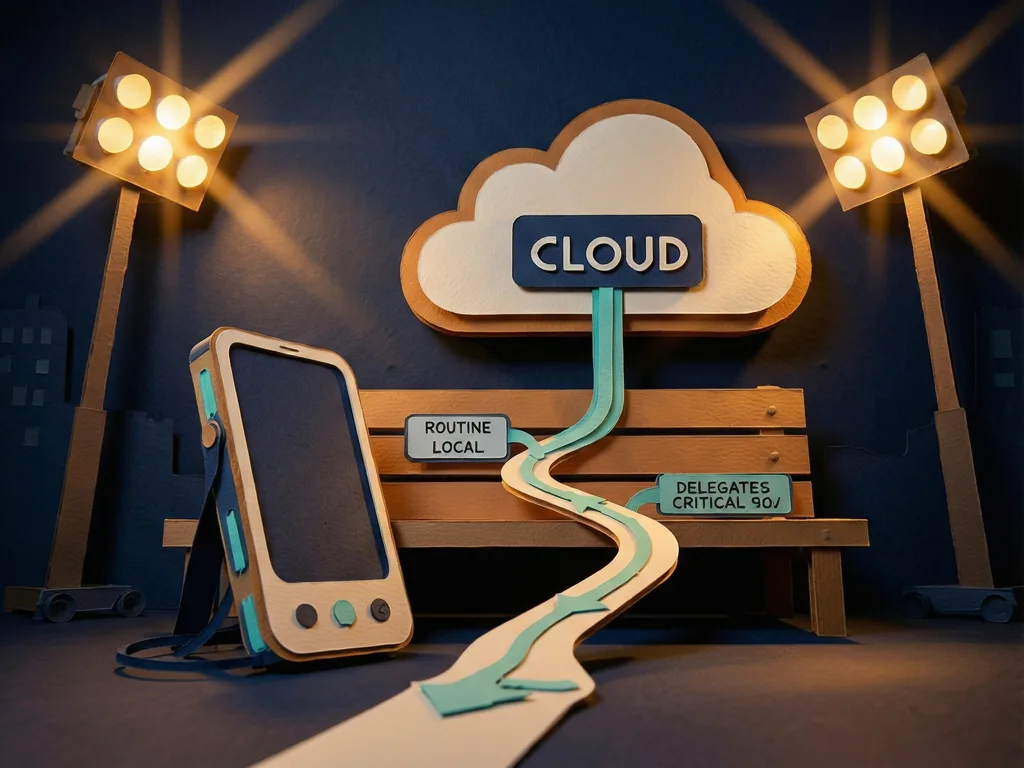
EdgeWise routes long-horizon agent steps from local SLMs to cloud LLMs only when critical, cutting inference costs by up to 62% on SWE-Rebench.
Granite Switch 4.1 combines chat, speech, and decisions in one model, reusing cache and adapters to cut GPU needs while adding specialists.
AI report says Model Context Protocol servers shift integration work to vendors; hooks, kits, and skills shape 2026 agent tooling.
Meta releases Muse Spark Open, an open-weight multimodal model with expert routing for coding, tools, one million context, and local inference.
Microsoft Research Focus #98 reviews AI translation, a solved geometry conjecture, coding-agent costs, and a 104-language tokenizer.
Microsoft Lazarus research shows hidden LLM backdoors via dormant neurons, making provenance, weight integrity, and Foundry controls essential.
NVIDIA Nemotron 3.5 Super VL and Bolt offer open, efficient agents for servers, edge devices, and local hardware, with privacy and customization.
NVIDIA Nemotron 3.5 Super Vision-Language is an open 120B multimodal model for enterprise agents, boosting reasoning, tool use, and efficiency.
OpenAI Dots and Meta Muse compare as persistent AI agents, separating models from agent stacks, execution loops, memory, sandboxes, and security.
MLExpert, a 35-billion Mixture-of-Experts agentic model, uses execution feedback to lift MLE-Bench Lite medal rate to 72.7%.
Gemini 4 Argon targets cybersecurity, coding, enterprise work with $2/$10 per million input/output, 1 million token limit, and top benchmarks.
Reflection's Beam is a 501 Billion Apache-2.0 open LLM with 1 Million token context for coding, agents, and GPU deployment.
Velox is a training-free attention router for video world models. It uses frustum slab geometry to speed chunked denoising and preserve visual memory.