
Assessing fairness in ChatGPT
A privacy-protected experiment tested how ChatGPT responds to different names using AI research assistants. Results show no dramatic bias, but subtle shifts in tone, examples, and cultural references occur based on name-associated backgrounds. The effect is mild, appearing in framing rather than answer quality. Users need not hide their names, while developers should test prompts across names at scale.
We ran a careful experiment to see how ChatGPT reacts to people's names. Using AI research assistants instead of real conversations, we kept everyone's privacy fully protected throughout the process. In this article, you'll learn what we discovered, why names can shape AI responses, and what this means for everyday users who type their own names into chatbots.
Why We Looked at Names at All
Your name carries information. It can hint at your age group, gender, cultural background, or where you grew up. Humans pick up on these signals all the time, sometimes without realizing it. Large language models like ChatGPT are trained on enormous amounts of human writing, so a natural question arises: do they pick up these signals too?
If a chatbot treats "John" differently from "Ayesha" or "Ming," that matters. It could affect everything from cover letter suggestions to gift recommendations. We wanted to understand whether this actually happens and how strong the effect might be.
How We Tested Without Putting Anyone at Risk
We didn't want real people's details floating through the testing process. Instead, we relied on AI research assistants to run the experiments. Here's the general approach in plain terms:
- We created a set of common first names drawn from different regions, cultures, and backgrounds.
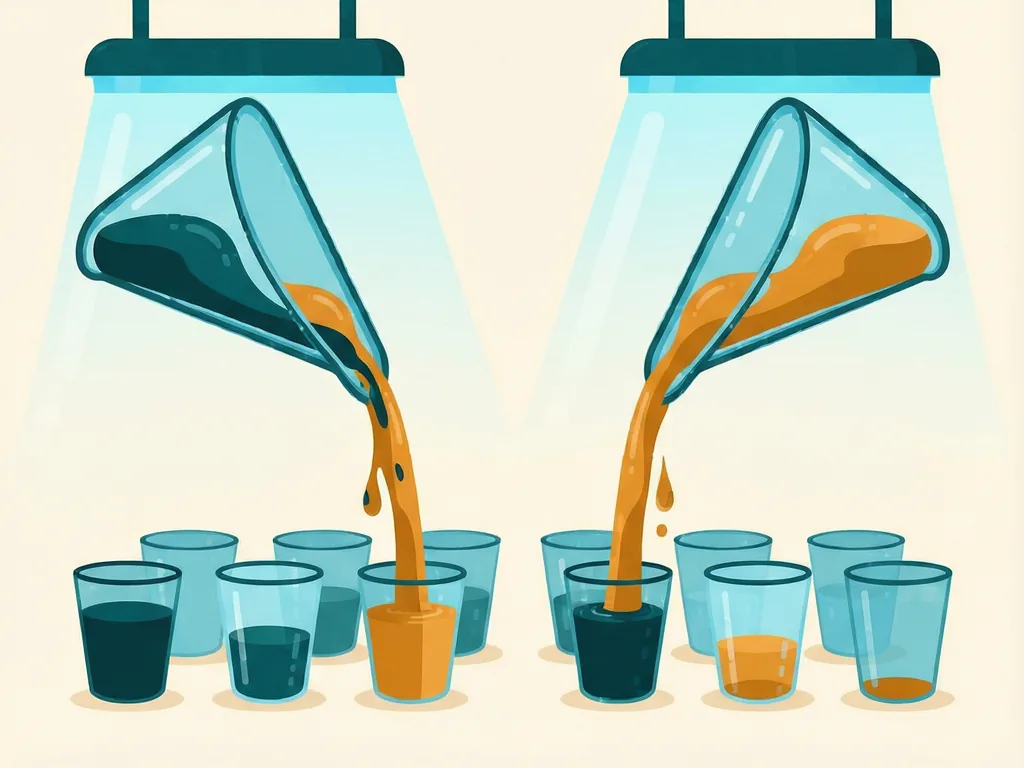
- The AI research assistants sent matched prompts to ChatGPT, identical except for the name included.
- We compared how the answers changed across those names.
- Every name used was either fictional or fully anonymized, so no private individual's data was involved.
This setup let us compare responses side by side. When everything except the name stays the same, any difference in the output points back to the name itself.
What We Found
The results were interesting rather than alarming. ChatGPT does not appear to make dramatic changes based on a name alone. It won't refuse to help someone or give obviously worse answers because of who they seem to be.
That said, we did notice subtle shifts. Names associated with certain regions or languages sometimes nudged the tone, examples, or cultural references in the answers. For instance, a name that suggests a particular country might lead the model to include local context or assumptions about language. These adjustments are often harmless and occasionally helpful, but they show the model is reading more into a name than most users expect.
The key takeaway: the effect is real but usually mild. It shows up in flavor and framing more than in quality or fairness of the core answer.
What This Means for You
If you use ChatGPT, here are a few practical points to keep in mind:
- You don't need to hide your name. The differences we saw were small and unlikely to hurt the usefulness of most answers.
- But you also don't need to share it. If a task doesn't require personal details, leaving them out keeps things simple and private.
- Context matters more than names. Clear instructions and specific requests shape responses far more than the name attached to them.
- Watch for assumptions. If an answer seems to assume things about you based on your name, just correct it. A quick "that's not my situation" usually fixes it.
For people building products on top of ChatGPT, the lesson is slightly different. If fairness matters in your application, it's worth testing how your prompts behave across different names before launch. Small biases can compound when a model is used at scale.
The Bigger Picture
Our experiment fits into a growing conversation about AI fairness. Researchers around the world have raised similar questions about how models handle names, accents, and dialects. OpenAI and other AI companies have published their own work on reducing bias, and models do seem to improve with each generation.
Still, no large language model is perfectly neutral. Because these systems learn from human-generated text, they inherit some of the patterns, assumptions, and stereotypes found in that text. Experiments like ours help keep this issue visible and push developers to keep improving.
The good news is that asking these questions is now easier and safer than ever. AI research assistants make it possible to run structured tests without exposing real users' information, which lowers the barrier for independent checks on AI behavior.
Final Thoughts
ChatGPT reacts to names in small, subtle ways rather than obvious ones. The model sometimes adjusts tone, examples, or cultural touches based on what a name suggests, but it doesn't deliver dramatically different help to different people. For everyday users, there's no strong reason to worry, though staying aware of these patterns is always smart.
If you're curious yourself, you can try a simple version of this test: ask ChatGPT the same question twice, once with your name included and once without, and compare the answers. It's a quick way to see how much your name actually shapes the conversation.
Comments (0)