
Distributed Async GRPO Training with LoRA on HF Jobs Using a Bucket and a Proxy—No NCCL Required
This post demonstrates a distributed asynchronous GRPO training setup using TRL v1.14's AsyncGRPOTrainer with LoRA on Hugging Face Jobs. The trainer and vLLM inference replicas run on entirely separate machines with no shared network, connected only via a Storage Bucket mounted as FUSE and a routing proxy. Since LoRA adapters weigh just a few megabytes versus gigabytes for full models, syncing is cheap. The recipe cut 500-step runtime from 3h27m to 53 minutes across five runs.
If you run reinforcement learning fine-tuning and want your training and inference workloads to live on entirely separate machines, this post is for you. We walk through a real setup built on TRL v1.14, where the new AsyncGRPOTrainer trains only a LoRA adapter and syncs just that adapter to vLLM replicas running as independent Hugging Face Jobs. The result: the same recipe that took 3 hours 27 minutes runs in 53 minutes for 500 steps across five runs.
Why LoRA fits reinforcement learning so well
LoRA support recently landed in TRL's AsyncGRPOTrainer with PR #7017 and ships in TRL v1.14. Instead of updating the full model, the asynchronous trainer now trains an adapter and syncs only that adapter to vLLM.
Thinking Machines's blog post "LoRA Without Regret" makes a compelling case that this is more than a shortcut: LoRA can match full fine-tuning on policy-gradient RL, even at rank 1. The intuition comes from information theory. The advantage function delivers roughly O(1) bits of useful signal per episode, so there simply isn't much to absorb per step. A rank-1 adapter has plenty of capacity for that.
There's a systems payoff too. A rank-1 adapter for a 1.5B model weighs a few megabytes, while the full model sits around 3 GB. Rather than shipping the whole policy to inference workers after every update, you ship the adapter. vLLM can also hold several adapters at once, which means older rollouts finish under the policy they started with while new rollouts pick up the latest version.
The challenge: separate Jobs with no shared network
TRL's AsyncGRPOTrainer already decouples training from generation, letting the trainer and vLLM run on different machines at their own pace. That's straightforward when both processes share a filesystem or can form an NCCL group, as on a single node or a Slurm cluster.
Hugging Face Jobs change the picture. A Job is essentially one container on one VM, so a single Job cannot spin up multiple nodes for a trainer plus a fleet of vLLM servers (each node tops out at 8xH200). With full-weight syncs, this setup would go nowhere: every update would mean moving gigabytes between machines, exactly the job NCCL does in a dense cluster, but Jobs can't talk across nodes. There's no shared local disk and certainly no shared localhost.
LoRA shrinks the sync to a few megabytes, and Storage Buckets solve the filesystem problem. Mounted as a FUSE volume via hf-mount, a bucket appears as a POSIX filesystem inside every container at the same path. No direct network path between Jobs is needed at all.
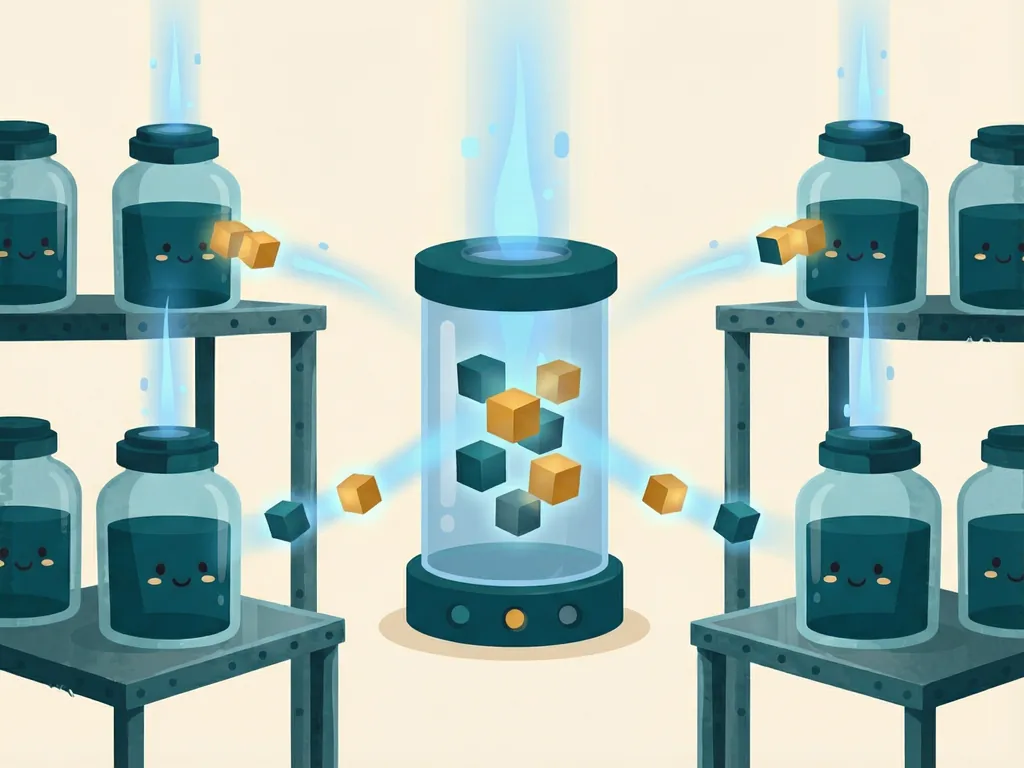
The architecture
The final setup is compact:
- A trainer Job running AsyncGRPOTrainer with LoRA and FSDP
- Two vLLM Jobs, each serving the base model plus the most recently published adapter
- A Storage Bucket mounted at the same path in all three, carrying the adapter from trainer to servers
- A proxy server that routes each rollout to the replica most likely to hold its KV cache and broadcasts adapter updates to every replica
Here's how the adapter-only sync works. The trainer never sends tensors to vLLM. Every few optimizer steps, it saves the adapter under `<output_dir>/.vllm_lora/trl-policy-v{N}`, publishes the directory with an atomic rename, and posts the path to vLLM's `/v1/load_lora_adapter` endpoint. The server loads the files from disk, after which rollout workers request `model="trl-policy-v{N}"`.
Nothing in TRL or vLLM had to change. The trainer writes to `/lora/<run>/.vllm_lora/`, the servers read from the same path, and the path in the POST request is valid inside every container thanks to the shared bucket mount. Checkpoints and the final adapter also live in the bucket, so a preempted trainer can resume without losing anything, even though Jobs themselves are ephemeral.
The three components
The vLLM replicas. Each replica runs one GPU with the stock `vllm/vllm-openai` image, pinned to v0.27.1 — treat the version as part of the recipe, since the flags and runtime LoRA endpoints are version-specific. The interesting knob is `--max-loras`, which follows from `max_staleness`. Every weight sync bumps the policy version, and `max_staleness` defines how many versions old a rollout sample can be before the trainer discards it. With `max_staleness=4`, a sample from v3 is still trainable while the trainer sits at v7, and rollouts started under v3 must finish under v3. So vLLM serves the current policy plus four predecessors, keeps `max_staleness + 1` versions registered, and needs one extra slot during the swap — giving `--max-loras 6`. With only five, vLLM would silently evict policies that still have rollouts in flight.
Versioned adapter names are deliberate. If the trainer republished under one fixed name, vLLM's prefix cache (keyed by adapter name) could reuse KV blocks computed under old weights, producing rollouts whose prefill came from one policy and whose decode came from another — invisible to the trainer except as the ratio drifting away from 1. A versioned name always means one set of weights, so a cached prefix can never match a newer version.
The dataset. The recipe uses `sail/Sanity-Test-R1D-1.5B`, from "Defeating the Training-Inference Mismatch via FP16" (Qi et al., 2025), with reproduction code in `sail-sg/Precision-RL`. The authors generated 40 answers per MATH problem with DeepSeek-R1-Distill-Qwen-1.5B and kept problems with a 20–80% success rate, yielding 1,460 questions — neither already solved nor hopeless, so the model gets a useful early training signal. It's also a great end-to-end sanity check: if a replica quietly serves the base model under an adapter name, the curve shows it within a few dozen steps, and the dataset cycles in under two hours. Hyperparameters come from the paper's LoRA scripts in `oat/scripts/lora`: Qwen/Qwen2.5-Math-1.5B, LoRA rank 1 with alpha 2, learning rate 4e-5, 8 samples per prompt, 128 completions per step, 3,000 max generated tokens, 4,096-token context.
The trainer. It uses the same `vllm/vllm-openai:v0.27.1` image with TRL installed. At init, TRL calls `/server_info`; if it finds a `lora_config`, it enables adapter-only sync (look for the log line "Adapter-only vLLM sync enabled"). Configurations vLLM can't serve directly — DoRA, `modules_to_save`, or a rank above `--max-lora-rank` — fall back to merged-weight sync with a warning.
The proxy. Two reasons for a small proxy at `127.0.0.1:8000` on the trainer Job:
- Exposed Job ports require an `Authorization: Bearer <HF token>` header on every request. The proxy adds it, so TRL stays unaware.
- Getting multiple GPUs generating normally means `--data-parallel-size > 1`, but TRL refuses adapter-only sync in that mode for good reason: a `/v1/load_lora_adapter` call only reaches the DP rank that answers it, leaving other ranks serving the base model under the new policy name. Since each replica here is its own machine, data parallelism moves up a level into the proxy.
Functionally, the proxy sends each completion request to one replica — chosen so the eight rollouts of a prompt land where their prefix is already cached — and broadcasts every state-changing request (adapter loads, pause, resume) to all replicas, so a policy name means the same thing everywhere.
Why KV-prefix routing pays off
Generation has two phases with very different cost profiles. Prefill processes the whole prompt at once, computing attention keys and values for every prompt token; decode produces one token at a time, each attending to all previous keys and values. That KV cache is causal: a token's KV depends only on what precedes it. Two requests sharing a prefix share that prefix's KV, so a replica that already holds it can skip part of the prefill entirely.
vLLM stores prefix cache entries in 16-token blocks, with chained hashes — the hash of block 3 represents blocks 1, 2, and 3 together, mirroring causal attention. The router seeds the chain with the adapter name too, since a prefix cached under policy v3 is useless for v4. Under GRPO, the rollout worker sends G identical-prompt requests (here G=8). If they all reach one replica, the first computes the prefill and seven reuse it. Round-robin routing would scatter half of them to replicas without the cached prefix, redoing prefill work and wasting GPU compute.
Tracking which replica holds which block hash, and steering each request accordingly, is what turns five runs at 3 h 27 min into a single 53-minute run for 500 steps — all without trainer and inference ever sharing a machine.
Comments (0)