
Embeddings make AI semantic search work by understanding meaning instead of just matching keywords.
This guide explains how embeddings enable semantic AI search, why keyword stuffing fails, and how 768 and 1536 dimensions affect accuracy and cost.
Key Takeaways
- Semantic search uses embeddings to understand meaning and user intent, rather than relying only on exact keyword matching, which fails when people use different phrasings for the same request.
- Embedding models convert text into numeric vectors that represent meaning, allowing similar phrases like “Get me a refund” and “I want my money back” to be found close together in vector space.
- Higher embedding dimensions provide more representational capacity, but they do not automatically produce better search quality; a well-trained 768-dimensional model can outperform a 1536-dimensional model for specific tasks.
- Embedding dimensions directly affect storage and memory costs: 768-dimensional Float32 vectors use about 3.1 KB per vector, while 1536-dimensional vectors use about 6.1 KB, which becomes significant at large scale.
Meta description: This AI retrieval explainer shows why keyword stuffing fails for assistants and how 768 and 1536 embedding dimensions affect accuracy and memory costs.
Tags: AI retrieval, semantic search, embedding dimensions, vector search, keyword search
Featured image: abstract friendly illustration of sentences becoming coordinate points in a space, no people, logos, or text.
For teams building production Retrieval-Augmented Generation (RAG) systems, Part 6 of the Production RAG Series explains why keyword stuffing fails when users speak naturally and how embedding models support semantic search. It also compares 768 and 1536 embedding dimensions and their storage and RAM costs.
The Old Search Trick No Longer Matches Human Requests
After Part 5, Advanced RAG Chunking, covered splitting documents with Parent-Document Retrieval, Breadcrumbs and Contextual Retrieval, Part 6 asks how to search chunks enriched with metadata.
For decades, Elasticsearch and Solr used lexical matching: stemming to connect "run", "running" and "runner", category filters and curated synonym lists. Sellers and creators adapted by packing titles with related terms, such as "Wireless Noise-Cancelling Over-Ear Headphones with Microphone — Bluetooth Travel Headset, 40-Hour Battery" and "Python Full Course for Beginners [2026] | Learn Python in 8 Hours". Tutorial creators also add tags such as "Python tutorial" and "coding crash course". Users typed keyword-heavy phrases such as "best coffee shop downtown wifi open late".
A customer searching "headset" may not match a product labeled "headphones" without a synonym rule or another signal. AI assistants changed the pattern. People ask in full sentences. The article compares three requests with one intent: "Get me a refund.", "I want my money back." and "Please reverse the charge on my card." They use "refund", "money back" and "reverse the charge". This vocabulary mismatch means a help center article saying "refund" may be missed by a "money back" search unless synonyms or other signals bridge it. Without them, results can be irrelevant, the right policy can be buried lower, or the customer can get nothing useful.
Teams cannot cover every variation with manual keyword stuffing and hand-crafted synonym dictionaries. Slang, colloquial phrasings, idioms, typos and different mental models make that impossible. Semantic search looks for meaning and intent, not exact word overlap.
Embeddings Turn Sentences Into Coordinates
A ten-year-old knows two phrases can mean the same thing; a computer has no such intuition. It does not speak English, Spanish or Hindi, and it does not inherently understand a dog, an apple or a refund request. It is a calculating machine, so comparing sentences requires turning meaning into numbers.
An embedding model is a neural network trained on billions of sentences from books, articles, code and web conversations. It learns relationships from context rather than rigid grammar rules. It converts text into a vector representation, a list of numbers that acts like a coordinate in meaning space.
The source uses GPS as a mental model: a restaurant at [Latitude: 37.7749° N, Longitude: 122.4194° W] and a coffee shop across the street at [37.7750, -122.4195] are close, while Tokyo is far. GPS coordinates describe physical places; embedding coordinates describe language patterns, and individual dimensions do not have simple labels.
Sample vectors are marked illustrative, not actual model outputs: "I want my money back" [0.342, -0.715, 0.821, 0.154, ... 0.092]; "Get me a refund" [0.351, -0.702, 0.808, 0.149, ... 0.088]; "How do I bake sourdough bread?" [-0.884, 0.129, -0.453, -0.612, ... -0.741]. A shorter sample is [0.34, -0.71, 0.82, 0.15, -0.09, 0.63, ...]. The first two vectors are close, showing semantic similarity even when words differ.
More Dimensions Add Room, Not Automatic Quality
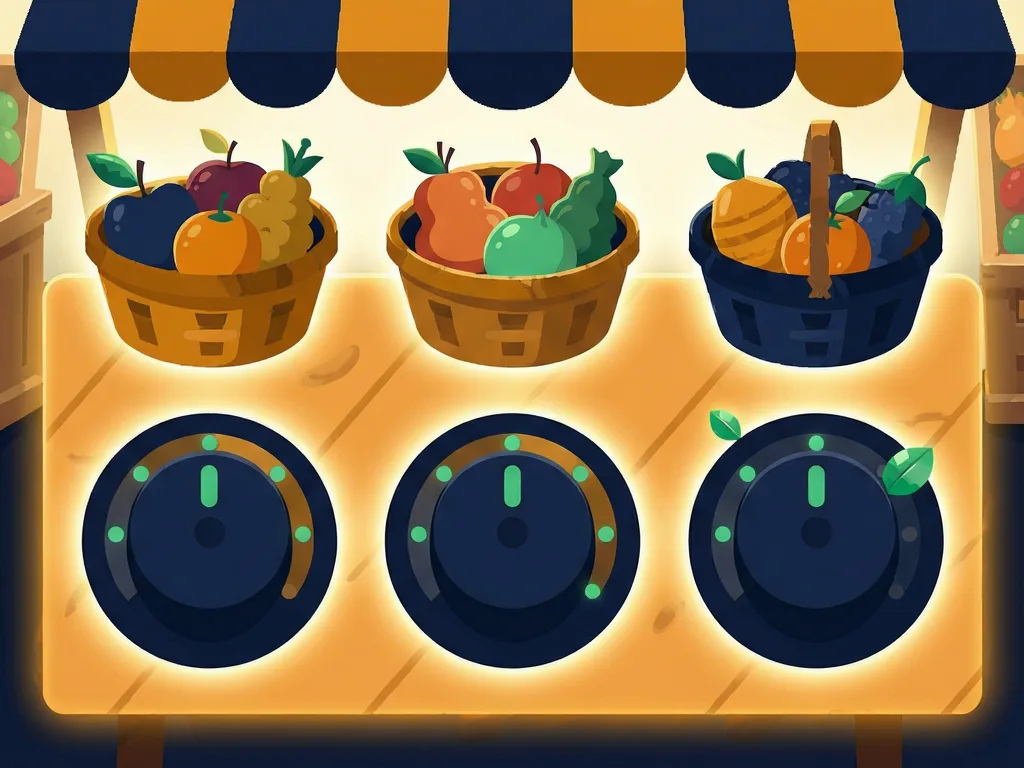
To explain dimensions, the article uses a fruit stand with three dials: sweetness from 0 to 10, sourness from 0 to 10 and crunchiness from 0 to 10. An apple is [8, 2, 9], a pear is [8, 1, 8] and a lemon is [1, 9, 2]. If red and green apples must be separated, it adds tartness as dimension 4, color hue as dimension 5 and juiciness as dimension 6.
The analogy shows why more numbers can give more room to represent information. Real embedding dimensions are learned from data and do not necessarily correspond to sentiment, formality, tense, domain, topic or intent. More dimensions do not automatically mean better semantic understanding. A common beginner assumption is that 1536 is double 768 and therefore always better. A well-trained 768-dimensional model may outperform a 1536-dimensional model on a specific task, especially for legal documents, medical papers, customer support queries or e-commerce catalogs.
768, 1536 and 3072 Dimensions Have Different Costs
Common 768-dimensional models include bge-base, all-mpnet-base-v2 and e5-base-v2. Common 1536-dimensional models include OpenAI text-embedding-3-small and text-embedding-ada-002. The article also notes text-embedding-3-large can use up to 3072 dimensions.
Storage math follows the numeric format. When each number is stored as a 32-bit floating-point number, or Float32, one number uses 4 bytes. A 768-dimensional vector needs 768 × 4 bytes = 3,072 bytes, about 3.1 KB. A 1536-dimensional vector needs 1536 × 4 bytes = 6,144 bytes, about 6.1 KB. The source frames the per-vector size as ~3.0 KB versus ~6.1 KB. Doubling dimensions doubles memory per vector in the same format.
For fast search, vectors may need to be held in memory. For 1,000,000 chunks, raw vectors occupy about 3.07 GB of RAM at 768 dimensions and about 6.14 GB at 1536 dimensions. If an organization indexes 20 million chunks, such as support tickets, Slack messages, emails and wikis, the raw 1536-dimensional vectors alone would occupy about 122.88 GB when stored as Float32. The source notes this is substantial data to store and search, while actual infrastructure depends on database and index configuration.
The next decision is not whether to use semantic search, but which model size to test against real retrieval tasks. Teams should evaluate how well different embedding sizes retrieve the information their application needs, rather than assuming 1536 is better than 768 simply because the vector is twice as long.
Comments (0)