
From Prompting to Composition: A Spatial Canvas Interface for Poster Creation
Compo adapts an image editing model to generate posters from a Spatial Canvas, using four bindings for layout, copy, references, and preserved visuals
Key Takeaways
- Compo is a poster generation model adapted from a pretrained image editing model, using a Spatial Canvas Interface to guide layout and copy.
- It relies on four bindings—Semantic, Identity, Text, and Pixel—to control concepts, reference assets, text placement, and preserved visual content.
- All design instructions are combined into one unified image input, making the canvas function like a spatial prompt rather than separate text commands.
- The interface offers a more visual and controllable workflow for designers, marketers, and content teams who need precise poster placement.
- The model’s practical value depends on how well it delivers stable layouts, readable text, and faithful preservation of existing visual elements.
Compo Uses Four Bindings to Generate Posters From Spatial Canvas
Meta description: Compo is a poster generation model adapted from a pretrained image editing model, using four bindings on a Spatial Canvas to guide layout and copy.
Tags: Compo, poster generation, Spatial Canvas, image editing model
Featured image: Abstract, friendly illustration of a canvas grid with four colored zones, square blocks, rectangular blocks, and simple layout guides; no real people, no logos, no text.
Compo is a poster generation model adapted from a pretrained image editing model, and it is aimed at designers, marketers, and content teams who need to control where visual and written elements land in a poster. Instead of asking those users to describe every placement in separate prompts, Compo interprets a Spatial Canvas Interface and its associated Text Specifications through four complementary forms of binding: Semantic Binding, Identity Binding, Text Binding, and Pixel Binding. The result is a single unified image input that carries layout instructions, reference assets, copy placement, and preserved visual content inside one canvas.
Four bindings turn canvas regions into instructions
The first binding is Semantic Binding. It connects a textual concept to a target region on the canvas. In practical terms, a designer can mark an area and give the model a concept for that area, such as a background theme or an object type, without writing a long prompt for each region. This makes the canvas function as a map rather than a list of separate text instructions.
The second binding is Identity Binding. It links a reference image to a region so that an existing element can keep its visual identity. That could be a product shot, a character, or a graphic asset that needs to remain recognizable. For teams that reuse brand material, this is a direct way to anchor a layout to an existing visual object instead of asking the model to recreate it from memory.
The third binding is Text Binding. It gives the model an exact text string and tells it where that string should appear. This is the binding most likely to matter for poster work, because a poster is not only an image; it also has headline text, subheadlines, labels, or calls to action that must appear in defined places. Text Binding turns those requirements into spatial targets that the model can interpret within the canvas.
The fourth binding is Pixel Binding. It places visual content directly on the canvas when that content should be preserved. This binding works at the pixel level, giving the model a clear instruction that certain content should remain in the generated poster rather than being replaced by a new visual approximation. Together, the four bindings cover concept, reference identity, copy placement, and preserved pixels.
A unified canvas becomes the prompt
In a typical image editing workflow, instructions are often split between a reference image, a mask, a text prompt, and a separate output. Compo compresses that process by rendering all elements directly onto the Spatial Canvas. Bounding boxes, reference images, and textual identifiers are not sent as separate disconnected signals; they become visible parts of one unified image input.
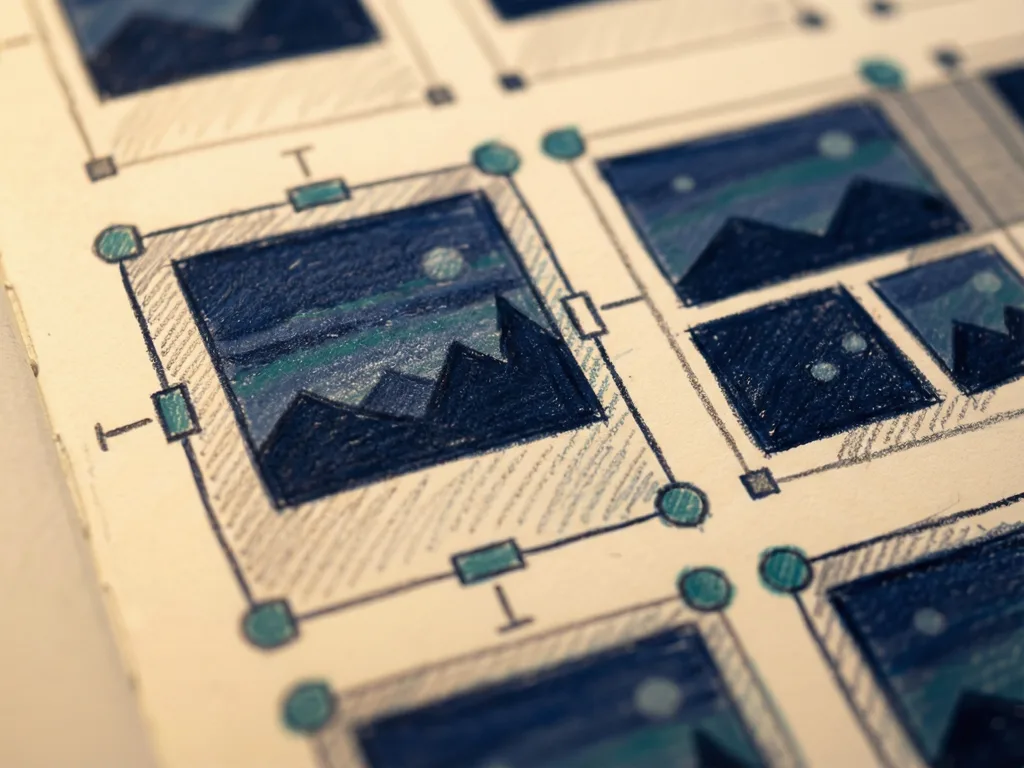
That means the model reads the canvas much like an editor reads a layout sheet. The boxes show where elements belong, the references show what should be preserved, and the text specifications show what copy should appear where. For non-experts, the appeal is that the interface can be visual and spatial rather than purely linguistic. A user can point with the canvas itself, and the model interprets those pointers through the four bindings.
Why adapting an image editing model matters
The introduction is notable because Compo is adapted from a pretrained image editing model without task-specific architecture design. Poster generation has usually been treated as a distinct creative task, but this approach reuses an editing backbone that already understands the relationship between an input image and a modified result. Image editing models often need to understand where changes should happen and which parts of an image should remain intact. Those skills are close to the needs of poster generation, where layout, consistency, and placement can matter as much as style.
The second reason is usability. A Spatial Canvas Interface with associated Text Specifications may make the model easier to control because users can arrange instructions visually. Instead of learning a complex prompt language, a designer can place boxes, attach references, and define text regions on the canvas. The model then interprets those cues through the binding system. This does not mean the task becomes trivial, but it moves the control surface from abstract text to a visual workspace.
What readers should watch next
For teams producing promotional graphics, the practical value of Compo depends on how cleanly the four bindings translate into stable layouts, readable text placement, and faithful preservation of reference assets. The system gives users one input surface for Semantic, Identity, Text, and Pixel instructions, which could reduce trial-and-error when a poster needs both a headline and a specific visual element in a fixed region. The next question is how well the adapted editing model handles the harder parts of poster design: typography, visual hierarchy, and the balance between generated content and preserved content.
Because Compo is introduced as a model built from an existing editing base rather than a fully new architecture, its long-term value will likely be judged by how much control it offers without requiring specialized design prompts or separate layout tools. For readers who make posters, infographics, or social graphics, the key takeaway is simple: Compo turns a canvas into a set of spatial bindings, and those bindings are the bridge between a designer's layout intent and a pretrained image editing model's generation behavior.
Comments (0)