
Simulating student learning improves AI tutoring.
StudentSim builds personalized AI student simulators from de-identified learner data to evaluate tutoring tools before real research tests.
Key Takeaways
- StudentSim builds personalized AI student simulators from de-identified learner records to help researchers evaluate and improve AI tutoring tools before testing with real students.
- The StudentSimEval benchmark assesses simulators in chess, second-language English writing, and mathematics using two goals: behavioral fidelity and responsiveness to tutor guidance.
- StudentSim outperforms leading baselines by better matching individual student behavior while also reflecting how students revise their responses after receiving guidance.
- The team emphasizes that StudentSim is a research tool, not a classroom product or a replacement for human teachers.
For researchers building AI tutoring tools, StudentSim creates personalized AI student simulators from de-identified learner records. It helps evaluate and improve tutors before real students test them. The StudentSimEval benchmark and evaluation protocol covers chess, second-language English writing, and mathematics, with one simulator adapted to each student. The team reports that StudentSim outperforms leading baselines while giving a useful feedback signal for tutor training. The authors emphasize it is not a product, is not deployed in classrooms, and is not meant to replace teachers.
Why student feedback is the missing loop
AI tutoring tools need student feedback to improve, but human studies are slow, costly, and difficult to scale. Researchers are exploring tutors that explain math problems, suggest writing edits, or guide chess positions. Teaching quality cannot be judged only from the tutor's answer. Developers must know what happens after guidance reaches a student: whether the original mistake was corrected, whether a hint helped reasoning, gave away too much, or whether another student would need different support. StudentSim approximates part of that feedback during research-stage training and evaluation, providing an early-stage research signal, not a substitute for real learner studies.
Two tests for a usable student simulator
A simple way to build a simulator is to ask a large language model to role-play a learner, such as an elementary-school student who struggles with math. The model can change tone and express uncertainty, but it may preserve a young voice while using knowledge and reasoning far beyond that student's level. That can make a tutor look effective only because the simulated student is too capable.
Knowledge tracing and behavior prediction models are grounded in real learning records and can estimate current knowledge, skills, and habits. Many were not built to take natural-language tutor guidance as input, so they may describe what a student has done without showing how the student would respond to an explanation, hint, or Socratic question.
StudentSimEval defines two education-inspired goals. Educators often separate what a learner can do alone from what they can do with support, an idea linked to Vygotsky's zone of proximal development. Behavioral fidelity asks whether a simulator matches a specific student's recorded responses on held-out problems. Guidance responsiveness asks whether it updates its response after reading tutor guidance. They are complementary: copying past behavior alone may help prediction but not show whether an intervention worked; always following the tutor may sound fluent but miss a student's strengths, weaknesses, and likely mistakes. Tutor training needs both starting point and guidance effect.
Building personalized simulators from sparse records
StudentSimEval is built entirely from publicly available learner datasets released for research use with de-identified records. No personally identifying information is used at any stage, and each simulator is trained only on the de-identified records of the student it represents.
Individual student data is often thin: a learner may have only a few essays, answers, or interactions. Training a separate model from scratch could overfit and force each simulator to relearn common domain patterns. StudentSim uses a two-stage pipeline. First, it trains on records pooled across many students in the same domain to learn common response formats, errors, and revisions after guidance. Then it specializes on one student's own records.
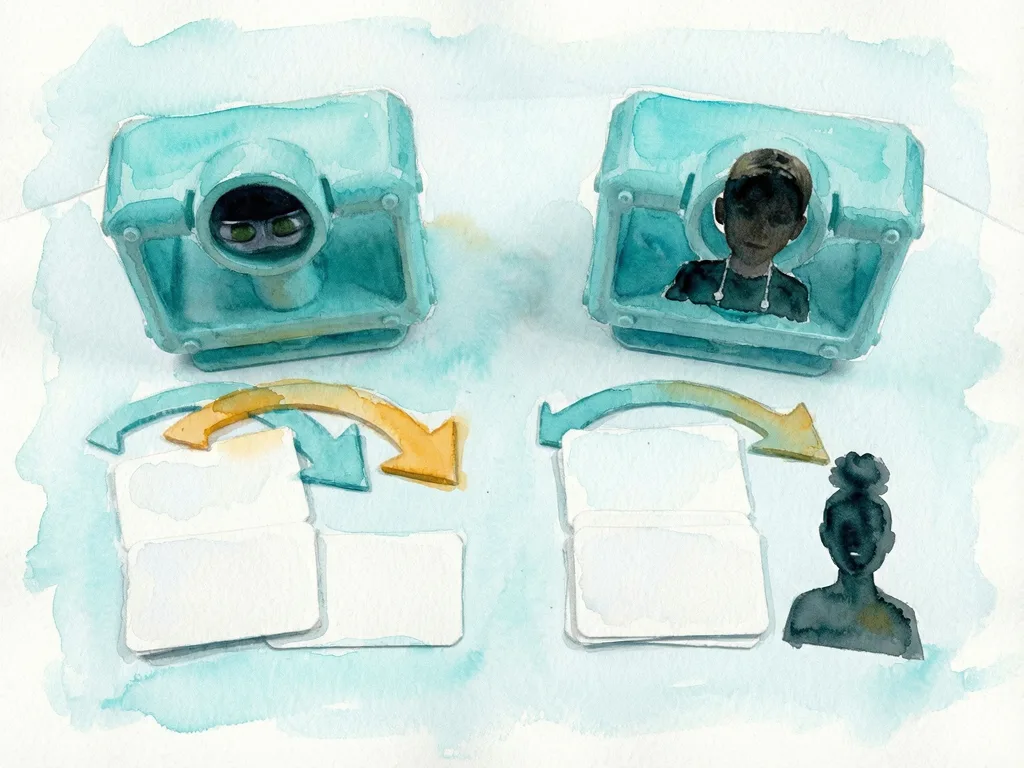
The evaluation uses three response types. In chess, the simulator predicts a player's next move and how that player may revise after coaching. In second-language English writing, it generates essays with error patterns matching a learner and predicts corrections after teacher feedback. In mathematics, it predicts a student's multiple-choice answer and whether the student updates after an explanation. All methods are compared on the same per-student training records and held-out evaluation records.
Chess results show a clearer signal than baselines
StudentSim outperforms leading baselines across the three domains. In chess, it reaches behavioral fidelity of 0.5150 and guidance responsiveness of 0.9067. GPT-5.4 reaches 0.2316 and 0.7186. Maia2, a chess-specific human move prediction model, reaches 0.4535 and 0.2721.
The comparison exposes each baseline's weakness. GPT-5.4 can respond to guidance but does not reliably match a specific student's behavior. Maia2 predicts human chess moves more closely but lacks a natural-language guidance pathway. StudentSim improves both independent behavior and response to guidance.
Using simulator feedback to train a tutor
The research also tests whether a trained simulator can provide feedback for tutor optimization. In a chess tutor reinforcement learning study, the tutor receives a position and a real student's previous wrong move, then generates guidance. The simulator's own parameters are held fixed; it reads the guidance and produces a revised move. The reward is based on improvement in move quality from the student's previous move to the simulator's revised move, using Stockfish as an independent chess engine signal.
The study compares a supervised fine-tuned tutor with no reinforcement learning, a tutor trained with GPT-5.4 as the simulated student reward source, and a tutor trained with StudentSim as the reward source. All use the same tutor policy, supervised starting point, and reinforcement learning setup. Human chess experts evaluate responses blind to condition.
The StudentSim reward produces the highest-rated tutor on all reported dimensions. The StudentSim-trained tutor reaches 90.5% accuracy, versus 75.7% for the no-reinforcement-learning baseline and 71.6% for the GPT-5.4 reward condition. It also receives higher ratings for guidance quality and personalization. The result is a proof of concept that simulators trained on real learner data can provide useful feedback for improving AI tutors.
What real learners are still needed for
StudentSim does not remove the need for real learners. Human studies remain essential for measuring learning outcomes, safety, usability, and classroom fit. Simulators help earlier: researchers can test tutor strategies, compare models, and refine training signals before more expensive studies with real students.
The broader direction is to build AI tutor systems that learn from student reactions, not only expert-written explanations or static correctness labels. StudentSim shows one path: use real learning records to train personalized simulators, evaluate independent behavior and response to guidance, and use them as scalable feedback sources for tutor training. Future work can extend this to longer learning trajectories, additional subjects, richer student profiles, and studies connecting simulated feedback with real learning outcomes. The paper and StudentSim training and evaluation code, including the StudentSimEval protocol, are publicly available.
Meta description: StudentSim trains personalized AI student simulators from public de-identified records to help researchers evaluate AI tutors in chess, writing and math.
Tags: StudentSim, AI tutors, student simulation, StudentSimEval, reinforcement learning
Featured image: Abstract friendly illustration of a stylized student profile card, a tutor chat bubble, and three small icons for chess, writing, and math, on a light gradient background; no real people, no logos, no text.
Comments (0)