
Create a Custom LLM Evaluation Harness in Python from the Ground Up
Build a Python LLM harness with golden cases, async runner, judge, and logger for product-specific, repeatable model testing.
Key Takeaways
- Public benchmarks do not validate product-specific LLM behavior, so a custom Python evaluation harness is needed to test prompts, responses, and scoring criteria under your own requirements.
- The harness is built from four modular components: a golden dataset of real test cases, an async inference runner, a judge layer, and a crash-safe logger.
- Keep inference separate from scoring: LiteLLM enables easy model switching and async concurrency, while the runner should return raw outputs only.
- Use deterministic judges for exact checks and LLM-as-a-judge for semantic evaluation; Pydantic enforces typed pass/fail outputs and prevents parsing failures.
- Append scored results and raw outputs to JSONL logs immediately, so you can re-score later without paying for another inference run and extend the harness into CI or dashboards.
Meta description: Learn how to build a custom LLM evaluation harness in Python with four modules: golden dataset, async runner, judge layer, and crash-safe logger.
Tags: LLM evaluation, Python, LiteLLM, Pydantic, AI testing
Featured image: Abstract friendly illustration of four connected Python modules, a test harness, and model outputs, no people, logos, or text.
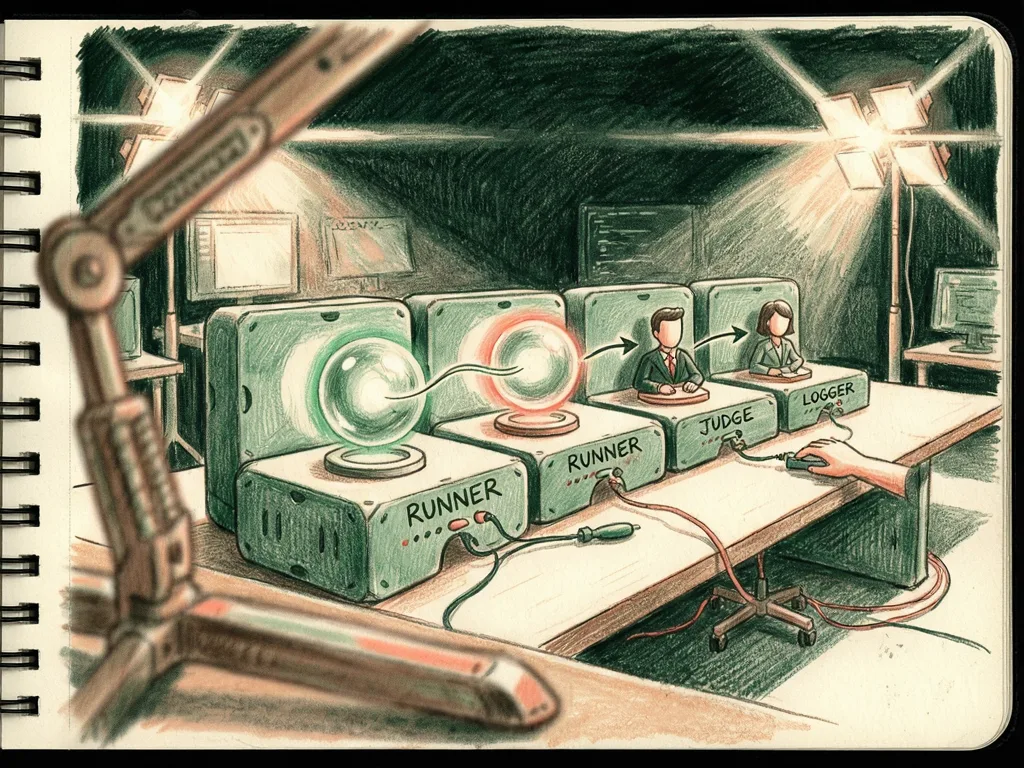
For developers and product teams that test large language models against their own requirements, a custom LLM evaluation harness in Python creates a repeatable workflow for sending prompts, recording responses, and judging them. The guide walks through building one from scratch in Python, using four modular components to give you full control over how your models are tested and scored: a golden dataset, an inference runner, a judge layer, and a logger.
Why public benchmarks are not enough
MMLU and GSM8K can show broad model ability, but they do not answer product-specific questions. Will a customer support agent obey your refusal policy? Will a retrieval-augmented generation pipeline retrieve the right context for your domain? To answer those, you need a pipeline you own.
A test harness in software engineering supplies inputs, records outputs, and compares them with a baseline. For large language models, the same structure runs many prompts and monitors pass rates, latency, and cost over time. A custom evaluation harness is a repeatable pipeline built around your test cases and your scoring criteria.
Prerequisites and dependencies
Python 3.10 or later is required, mainly because native asyncio support lets evaluations overlap instead of waiting for each API call in sequence. The package list is deliberately small.
LiteLLM provides one calling pattern for OpenAI, Anthropic, Google, and other model backends. Changing the model under test becomes a one-string edit rather than a runner rewrite. Pydantic forces the judge layer to return typed fields, not free text. The standard library handles the rest, with asyncio for concurrency and json for logging.
Step-by-step guide to building the harness
- Build a golden dataset from real user inputs. A golden dataset is a structured list of test cases that pairs each input prompt with an expected outcome. Every other component depends on it. Begin with 20 to 50 cases pulled from real user logs or known failure modes. Desk-made examples often sit on the happy path, while real inputs are messier, and the harness exists to catch that mess. Each case needs a unique id for cross-run tracking, the input sent to the model, and an expected_concept for the scorer to check. Short, unambiguous expected_concept values prevent unreliable scores. Make it your own by adding category tags, difficulty levels, or metadata about where a case originated. The structure is a starting point, not a ceiling.
- Write the inference runner. The runner loops over cases, calls the model, and returns the raw response. Because LiteLLM sits underneath, you can target GPT-4o, Claude 3.5 Sonnet, or a locally hosted model by editing one argument. Use num_retries=3 and timeout=30 as the minimum reliability settings for production evaluation runs. For full-dataset concurrency, use await asyncio.gather(*[run_case(c, model) for c in cases]). This starts all cases in parallel and reduces wall-clock time on large datasets. Keep scoring out of the runner: it should return raw outputs only. That separation matters later.
- Score the output with a judge layer. The judge receives each runner result and answers one question: pass or fail. Choose the judge based on the test. A deterministic judge is fast, cheap, and consistent when you need a specific string, format, or pattern. An LLM-as-a-judge costs more and runs slower, but it can evaluate meaning instead of exact text. A reply such as "this operation would permanently delete your data" should pass a refusal test even without the word "refusal." Pydantic requires the judge to return a valid passed boolean, not prose. Without that guard, a response like "I think it passed" can break parsing. These judges are intentionally bare-bones. Tailor them by adjusting the grading rubric, adding partial scoring, or sending different categories to different judges; that tailoring makes the harness useful for a specific project.
- Log results to disk. Write each scored result to a .jsonl file immediately. Append-only line-delimited JSON is a common evaluation log format because it survives crashes: if the runner stops before the dataset ends, the earlier results remain. Keep raw_output next to the score. Later, after improving the judge's rubric, you can re-score the same outputs without another inference run. On a 500-case dataset against a paid API, that avoids wasted time and cost.
What the harness changes for teams
The result is a working evaluation harness built from four modules, two dependencies, and roughly 60 lines of Python. The golden dataset defines good. The runner gathers raw outputs without scoring bias. The judge applies the method that fits each case. The logger separates inference from scoring so grading changes do not require another expensive inference pass. Each module is minimal enough to inspect and extend, not a black box to copy-paste.
The design can grow without a rewrite. Add latency and token cost fields to log records. Connect the harness to a continuous integration and continuous delivery pipeline so regressions surface on every model update. Aggregate .jsonl logs into a dashboard. Replace the simple judge with a rubric-based grader.
The source also points to related coverage on algorithm test harnesses, PyCaret model pipelines, comparisons of LLM evaluation frameworks, LLM evaluation metrics, and fine-tuning Llama 3 for custom tool calling.
Common mistakes
- Treating public benchmarks as enough. MMLU and GSM8K can show broad capability, but they will not tell you whether a specific refusal policy, domain context, or product prompt works.
- Using invented test cases. Start with real user logs or known failure modes; synthetic happy-path examples hide the messy inputs that cause regressions.
- Vague expected_concept values. If the expected outcome is ambiguous, scores become unreliable.
- Mixing inference and scoring. If raw outputs are not logged, a later rubric change forces another expensive API run.
- Leaving judge temperature unset. LLM judges are non-deterministic by default. Set temperature=0 on judge model calls to reduce variance.
- No concurrency cap. LiteLLM's num_retries handles transient failures, but sustained rate limits require wrapping asyncio.gather with asyncio.Semaphore(10) to limit simultaneous requests.
- Routing every case to the LLM judge. Run deterministic scoring first and route only failures to the more expensive judge. Most straightforward cases resolve without an API call, and you save expensive grading for genuinely ambiguous outputs.
- Not customizing judges for categories. Bare-bones pass/fail judges are a foundation, but real projects often need different rubrics, partial scoring, or category-specific routing.
Comments (0)