
An explanation of speculative decoding shows how any LLM can achieve three times faster inference.
Speculative decoding speeds up LLM inference by drafting and verifying tokens in parallel for 2 to 3 times faster output while preserving quality.
Key Takeaways
- Speculative decoding speeds up LLM inference by 2x–3x without retraining, changing model weights, or reducing output quality, by pairing a fast draft model with a larger target model that verifies multiple candidate tokens in parallel.
- Normal autoregressive LLM generation is slow because each token requires loading large model weights from memory, while speculative decoding amortizes this cost by checking several candidate tokens in one target-model pass.
- The method preserves the target model’s exact output distribution using probabilistic acceptance and correction, so the speedup comes from accepting multiple tokens, not from approximating the main model.
- Real-world gains depend heavily on the draft-target pair and acceptance rate; well-matched models can achieve 70%–80% acceptance on suitable tasks, while poorly matched drafts may add overhead and become slower.
- Variants such as Medusa, Eagle, and Prompt Lookup Decoding reduce or remove the need for a separate draft model, improving simplicity or throughput but sometimes trading away the original strict distributional guarantee.
Meta description: Speculative decoding speeds up LLM inference by drafting candidate tokens and verifying them in parallel, often delivering 2x to 3x faster output.
Tags: Speculative Decoding, LLM Inference, GPU Memory Bandwidth, Model Serving, Medusa Eagle

Speculative decoding is an inference technique for large language models that can make text generation 2x to 3x faster without retraining, changing model weights, or lowering output quality. It matters for teams serving chatbots, coding assistants, customer service bots, or real-time agents, because those applications are constrained by the cost of producing each token. The method works by pairing a fast draft step with a parallel verification step, so a large model can process several candidate tokens at once while preserving its own output distribution exactly.
Why ordinary LLM generation is slow
Large language models generate text autoregressively. That means the model reads the tokens produced so far, runs a full computation across its parameters, emits one new token, then repeats the process for the next token. For a long answer, that serial pattern can dominate latency.
The limiting factor is often not raw math speed. Modern AI hardware, such as NVIDIA H100 GPUs, can perform the matrix operations needed for model inference very quickly. The problem is that the model's billions of parameters live in GPU memory, and the weights must be moved into the processor before each token can be produced. Engineers call this condition memory-bandwidth bound. In that state, compute units spend much of their time waiting for data, so adding more processor throughput does not necessarily make token generation faster.
Speculative decoding changes the work pattern. Instead of paying the expensive memory-load cost once per token, it tries to load the large model's weights once and use that pass to check multiple candidate tokens.
The draft and verify loop
The standard implementation uses two models. The draft model is small and lightweight, so it can produce a short sequence of candidate tokens quickly. Typical sequences are 4 to 8 candidate tokens. The draft model still generates autoregressively, but because it has far fewer parameters, it can move through that step much faster than the main model.
The target model is the larger, higher-quality model whose output users expect. It receives the candidate sequence and scores it in one batch operation. Instead of evaluating one token at a time, it checks the whole draft in parallel. That matters because GPU compute is well suited to parallel work, so scoring a small batch may take only slightly longer than scoring a single token.
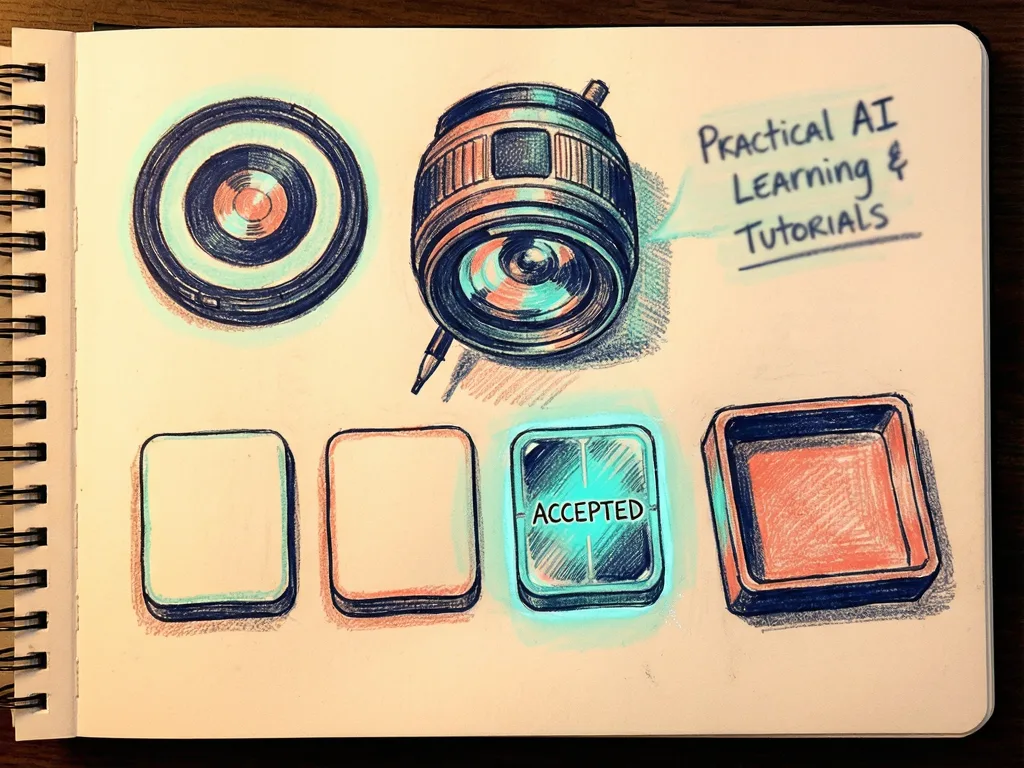
The acceptance rule is probabilistic. For each candidate, the target model compares its own confidence with the draft model's confidence. If the target model is at least as confident as the draft model, the candidate is accepted. If the draft model was more confident, the candidate is accepted with a probability that decreases as the difference grows. If a token is rejected, the system samples a corrected token from an adjusted distribution that accounts for the gap between the two models.
That correction is the key guarantee. The final output has the same probability distribution as if the target model had generated every token by itself. The speedup comes from accepting several tokens in one verification pass, not from approximating the target model.
What the best and worst cases look like
In the best case, every candidate in the draft is accepted, and the target model can also produce one additional token at the end. This can yield 5 to 9 tokens for roughly the cost of one target model pass.
In the worst case, the first draft token is rejected and replaced. That still costs the draft model's generation time, so it can add slight overhead compared with standard decoding. This is important for production teams: a poorly matched draft and target pair may not simply be neutral. It can be a little slower.
Real-world speedups depend heavily on acceptance rate. When well-matched model pairs reach acceptance rates around 70 to 80 percent on common tasks, the practical gain is often 2x to 3x. Tasks with predictable or repetitive text tend to produce higher acceptance rates and larger gains.
Variants that remove the separate draft model
The original two-model setup is effective, but it adds memory and engineering overhead because a separate draft model must be maintained. Several modern variants keep the draft-and-verify idea while changing how candidates are produced.
Medusa modifies the target model by attaching multiple prediction heads to its final layer. Each head predicts a different future token position, allowing the target model to generate its own candidate sequences without an external draft model.
Eagle, or Extrapolation Algorithm for Greater Language-model Efficiency, uses the target model's internal hidden states to predict future tokens. Hidden states carry richer contextual information than final output tokens alone, which can help acceptance rates on complex or domain-specific text.
Prompt Lookup Decoding requires no secondary model. It scans the prompt and conversation history for phrases likely to reappear in the response and uses those phrases as draft candidates. This is especially useful for code editing and document summarization, where output often echoes vocabulary and structure from the input.
Some of these variants trade the strict distributional guarantee of the original method for simpler implementation or higher throughput. In practice, the impact on output quality is generally negligible, but teams should still choose deliberately based on their accuracy and latency requirements.
When to enable it, and when to be cautious
Speculative decoding is available as a built-in option in inference frameworks such as Hugging Face text-generation-inference, vLLM, and llama.cpp. For many teams, enabling it is closer to a configuration change than a research project.
It is most useful when outputs are long, when the system serves one request at a time rather than large batches, and when the prompt and response share vocabulary or structure. Question answering, document summarization, and code completion are examples where the technique can produce strong gains.
High-throughput batch serving is different. In heavily batched settings, draft tokens consume memory and compute that could otherwise be used to serve additional requests. Speculative decoding can therefore hurt throughput even if it helps per-request latency. This is the main trade-off to understand before turning it on in production.
Common mistakes
The first mistake is assuming speculative decoding always improves throughput. It often improves single-request latency, but large batches may see less benefit or even a throughput loss.
The second is treating draft model quality as a minor detail. If the draft model rarely matches the target model, acceptance rates fall, overhead grows, and the speedup disappears.
The third is ignoring the workload. Repetitive, structured, or prompt-echoing tasks are good fits. Highly variable tasks may produce lower acceptance rates, making the gain smaller.
The practical takeaway is simple: speculative decoding is a hardware-aware generation strategy. It does not make the model more capable. It reduces the time the GPU waits for memory by turning single-token generation into a batched verify-and-accept loop. When the draft and target models fit the task, it can deliver 2x to 3x faster inference while keeping the target model's output distribution exactly intact.
Comments (0)