
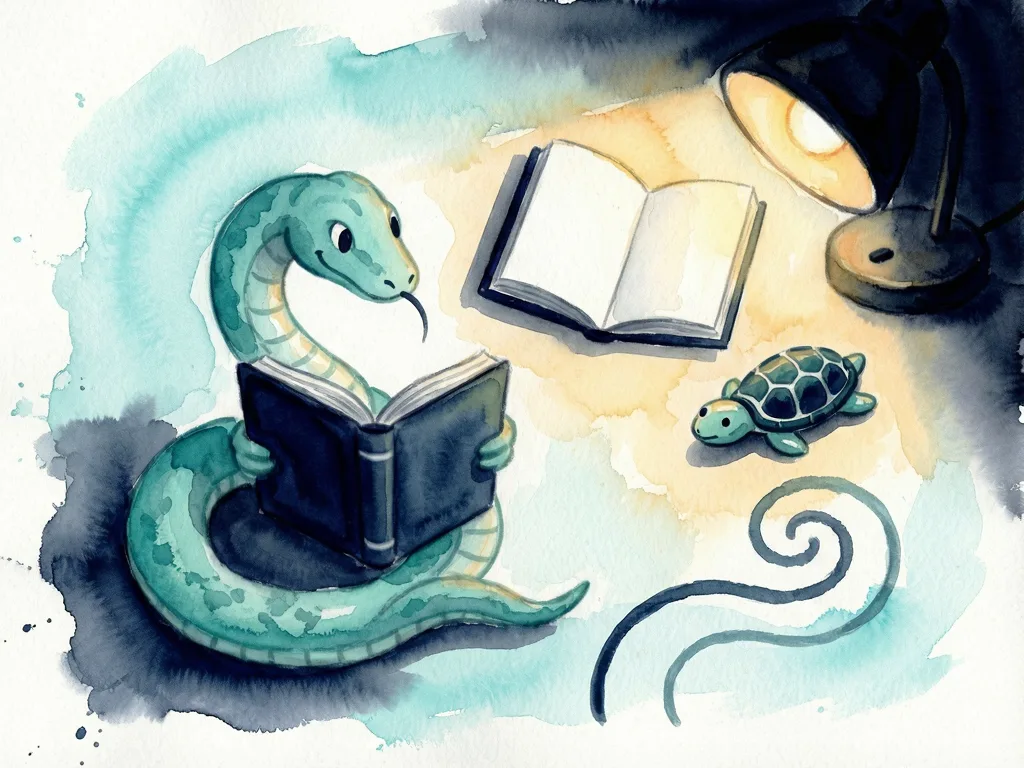
GPT-6.1 Terra Creates an Illustration of a Python Reading a Book
Real Python tested GPT-6.1 Terra on five Python tasks: turtle drawing, modern idioms, latest release, unrelated edits, and hallucination.
Key Takeaways
- Real Python informally tested GPT-6.1 Terra on five everyday Python tasks: a turtle drawing, a modern Python CLI tool, the latest Python version, unrelated edits, and a fake function question.
- The model completed the turtle drawing with 2853 commands in 110 lines, but the result reflects execution output, not artistic quality.
- GPT-6.1 Terra’s code mostly pinned Python modernity to 3.10, while its newest used feature was 3.11, showing a gap between claimed recency and usable code features.
- It reported Python 3.14.5 as the latest version, made no unrelated edits in the script task, and sidestepped the fake `itertools.flatten()` question by showing a real alternative without calling it out as nonexistent.
- The full five-task run cost $0.03, used default reasoning with 2.6k thinking tokens, produced 6.3k output tokens, and took 1 min 16 s.
Meta description: Real Python tested GPT-6.1 Terra across five everyday coding tasks, including a turtle drawing, modern Python checks, and hallucination spotting.
Tags: GPT-6.1 Terra, Real Python, OpenRouter, Python AI benchmark, coding assistant
Featured image: 
Python developers who want a compact, low-cost look at how GPT-6.1 Terra handles everyday coding work can use Real Python's informal five-task comparison. The model was asked to draw a python reading a book with the turtle module, write a small command-line tool, identify the latest Python release, edit a 50-line script, and respond to a question about a made-up function. The run was recorded as openai/gpt-6.1-terra via OpenRouter, at default reasoning settings, with no system prompt and the returned code left unchanged.
What the five tasks measure
Real Python used the same prompts and no system prompt for each model, judging the returned code and replies. These informal tests explore a few habits that can affect everyday Python work.
The snake task asks for a Python turtle program that draws a python reading a book. The script is run under a virtual display, and every drawing command is recorded, so the picture is whatever came out, arrow and all.
The Python modernity task asks for a small command-line tool. The evaluation reads which features it uses, such as list[str], tomllib, and Path.walk(). The score is the latest Python version for which all required checkpoints pass or do not apply. The same command-line tool is also used to count how many checked idioms came out modern, out of those that applied to the model's code.
The latest-version task asks which Python release is newest. Whether the answer is up to date is recorded, but that does not establish the model's training cutoff.
The unrelated edits task asks the model to add an --ext option to a 50-line script. The script works but has ten spots that are easy to tidy up, such as an unused import, % formatting, and a typo in a comment. None of them is part of the task. The evaluation lists the spots the model changed anyway, and the diff can be inspected to see whether those changes were useful.
The made-up-function task asks, "How do I use itertools.flatten()?" That function does not exist. Caught it means the model said so. Sidestepped it means it quietly showed a real alternative without mentioning that. Fell for it means it invented an answer.
The test also records reasoning effort and cost. Reasoning effort is the thinking setting used. default means the model's own setting was left alone, which is how most people use it, and the token count is how much thinking the API reported. Cost is what the API charged for all five tasks in US dollars. A ≈ would mean the API did not report a bill, so the tokens were priced at the model's list price. The overview page shows the same Python feature score alongside that version's release year, because code can use newer features and still receive a lower score.
How GPT-6.1 Terra performed
| Task | Result | Detail |
|---|---|---|
| The snake | Drew it | 2853 drawing commands, 110 lines of code |
| How modern its Python is | Python 3.10 (2021) | pinned by datetime_utc; newest feature used: Python 3.11 |
| Modern idioms | 6 of 14 | of the checkpoints that applied to its code |
| Latest Python version reported | 3.14.5 | the reply is quoted below |
| Unrelated edits | 0 of 10 | left every unrelated spot alone |
| Spots a made-up function? | Sidestepped it | showed a real alternative without saying the function is made up |
| Reasoning effort | default | 2.6k thinking tokens over all five tasks |
| Cost | $0.03 | for all 5 tasks, as billed by the API |
| Response time | 1 min 16 s | 6.3k output tokens |
Why the results matter
The snake drawing completed the task with 2853 recorded commands in 110 lines of code, but the number does not describe artistic quality. It records what the returned script emitted under the virtual display.
The Python modernity result shows a split between reported recency and usable features. GPT-6.1 Terra landed on Python 3.10 (2021), pinned by datetime_utc, while the newest feature used in its code was Python 3.11. That gap is why the overview page pairs the Python feature score with the release year: newer features can appear in code without lifting the full score.
The latest Python version answer was 3.14.5, as quoted in the reply. For developers, the useful part is not the number alone, but the caveat that this task checks answer freshness, not training cutoff.
The unrelated edits result is perhaps the most practical signal in the run. GPT-6.1 Terra changed 0 of 10 tidy-up spots and left every unrelated spot alone. That behavior matters when someone asks for a narrow change and does not want the assistant rewriting imports, formatting, or comments outside the request.
On itertools.flatten(), the model sidestepped rather than caught the fake function or fell for it. It showed a real alternative without saying the function is made up. That is a quieter answer, but it still avoids inventing a nonexistent API.
The cost and latency give the test its practical shape. The API billed $0.03 for all 5 tasks, with default reasoning producing 2.6k thinking tokens over all five tasks. The reply also used 6.3k output tokens and took 1 min 16 s.
Where the test sits
Real Python presents this as an informal model comparison, not a fixed benchmark. It says "New Model Drops? We Run the Bench," and invites readers to join the Real Python Newsletter to get every new AI benchmark run and the full write-ups in their inbox, plus weekly Python tutorials, the moment they land.
The page also lists a learning path called Python Coding With AI, with 12 Resources and skills including Cursor, Claude Code, AI-Assisted Development, Context Engineering, and AI Code Review. It promotes Python Tricks, a short and sweet Python trick delivered to the inbox every couple of days.
The full benchmark article is at https://realpython.com/ai-benchmark-gpt-6-1-terra/.
Comments (0)