
Refined Approaches for Training Consistency Models
Consistency models are a new family of generative models that can produce high-quality samples in a single step. They combine the speed of GANs with more stable, non-adversarial training, offering a middle path between GANs and diffusion models. This article explains how they work, their advantages in speed, cost, and interactivity, and their current limitations.
If you have heard about diffusion models but find their slow, multi-step generation frustrating, this introduction to consistency models is for you. By the end, you will understand what consistency models are, how they differ from diffusion models and GANs, and why their one-step sampling ability matters for the future of generative AI.
What Are Consistency Models?
Consistency models are a young and rapidly evolving family of generative models. Their defining feature is speed: they can produce high-quality data in a single step. This is a big deal, because most modern generative models require many iterative steps to turn random noise into a finished image, audio clip, or other sample.
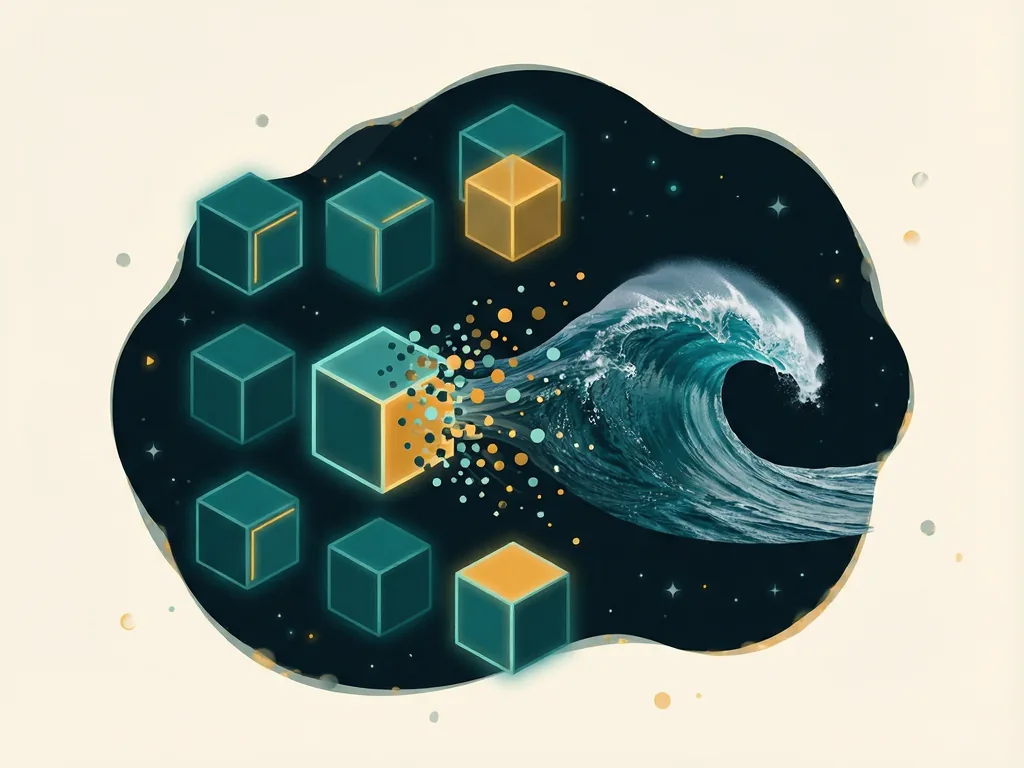
The key idea behind consistency models is learning a "consistency function" that maps any point along a diffusion model's trajectory directly back to the origin of that trajectory. In simpler terms: during training, a diffusion process gradually turns clean data into noise. A consistency model learns to jump from any stage of that noisy process straight to the final clean result. Once trained, this means you do not have to walk through dozens of intermediate steps — you can leap directly to the answer.
How They Differ From Diffusion Models and GANs
To appreciate why consistency models are exciting, it helps to compare them with the two dominant approaches in generative AI.
Diffusion models (the technology behind tools like Stable Diffusion and DALL-E) generate images by starting with pure noise and gradually denoising it over many steps — often 20 to 50 or more. This produces excellent quality but makes generation slow and computationally expensive. Each step requires a full pass through a neural network.
GANs (Generative Adversarial Networks) generate data in one step by pitting two networks against each other: a generator that creates samples and a discriminator that judges whether they look real. GANs are fast, but training them is notoriously unstable, and the adversarial setup can lead to problems like mode collapse, where the model produces a limited variety of outputs.
Consistency models offer a middle path. Like GANs, they can sample in one step. But unlike GANs, they do not require adversarial training. There is no generator-versus-discriminator battle, which means training tends to be more stable and the well-known pitfalls of GANs can be avoided.
Why One-Step Sampling Matters
The ability to generate in a single step has practical consequences:
- Speed: What takes dozens of network evaluations in a diffusion model can happen in one, dramatically reducing latency.
- Cost: Fewer steps mean less compute, which translates into lower energy use and cheaper inference at scale.
- Interactivity: Real-time applications — live editing, instant previews, on-device generation — become far more feasible when a sample appears almost instantly.
- Flexibility: Consistency models can also be run with a few steps instead of just one, giving users a dial between speed and quality.
This flexibility is worth emphasizing: a consistency model trained properly can choose how many steps to use at generation time, something rigid one-shot generators cannot easily offer.
The Trade-Offs and Current Limitations
Because consistency models are a nascent technology, they come with caveats. Sample quality in a single step may not always match what a full diffusion model achieves with many refinement steps. Training them well requires careful design choices, and the research literature in this area is still developing quickly. As with any emerging method, best practices are still being established, and results can vary depending on the data type and model configuration.
It is also fair to say that diffusion models remain the industry standard today, supported by mature tooling and large ecosystems. Consistency models are best understood as a promising direction that could reshape how fast generative AI becomes, rather than a finished replacement for everything that came before.
The Bigger Picture
Consistency models represent a broader trend in generative AI research: closing the gap between quality and speed. If the field can reliably train models that match diffusion-level quality in one or two steps, generative tools could become as responsive as any everyday app — no more waiting bars while your image renders.
Key Takeaways
- Consistency models are a new family of generative models capable of one-step, high-quality sampling.
- They avoid adversarial training, setting them apart from GANs.
- They borrow ideas from diffusion models but skip the slow iterative denoising at generation time.
- Their main promise is speed: lower latency, lower cost, and real-time creative applications.
- As a nascent technology, they still have open questions around training and quality, but they are one of the most interesting directions in modern generative modeling.
If you are following the evolution of generative AI, consistency models are a name worth remembering.
Comments (0)