
Adaptive Computation Turns LLMs into Efficient System One Models
NESTONE trains one LLM with early exits and shared layers, letting decisions stop at needed depth and cut compute while keeping accuracy.
Key Takeaways
- NESTONE makes LLM-based decision models adaptive by allowing them to exit early instead of always running the full backbone.
- It jointly trains a full model with shorter prefix submodels through self-distillation, while sharing final layers and the decision head.
- A lightweight gate reads hidden states at each exit to decide whether more computation is needed, so easy decisions use fewer layers.
- Across seven decision benchmarks, NESTONE matches or outperforms independently trained models while improving accuracy-efficiency trade-offs.
- The results suggest decision-relevant information is concentrated in early and intermediate layers, making model depth a tunable resource.
Meta description: NESTONE trains an LLM with early exits and shared final layers, so decision tasks can use fewer layers while keeping accuracy across seven benchmarks.
Tags: NESTONE, LLM, adaptive computation, decision models, self-distillation
Featured image: A layered neural network with early exit gates and shared final layers, without text, people, or logos.
NESTONE reduces LLM decision-task computation without training a smaller model from scratch; one trained model chooses depth per decision while preserving key layers.
Why Full Depth May Be Overkill
System One decision LLMs replace the language modeling head with a decision head but keep the full backbone, so every decision pays for all layers even if only part is needed.
Needed information concentrates in intermediate layers: early layers build essential features, while the final six layers can be removed without loss. Independently trained smaller models largely mimic the full model rather than develop specialized decision capabilities, so shrinking the backbone is not enough; sharing computation across depths lets early exits reuse useful layers rather than become separate weaker models.
How NESTONE Exits Early
NESTONE jointly trains a full model with prefix submodels that share final layers and a decision head through self-distillation. The full model’s behavior trains shorter submodels to align when stopping early.
A lightweight gate reads the hidden state (the representation built up to that layer) at each exit to decide whether more computation is needed. If the representation suffices, the model exits; otherwise it continues. This adaptive computation lets one model operate at multiple depths instead of forcing every input through the same path.
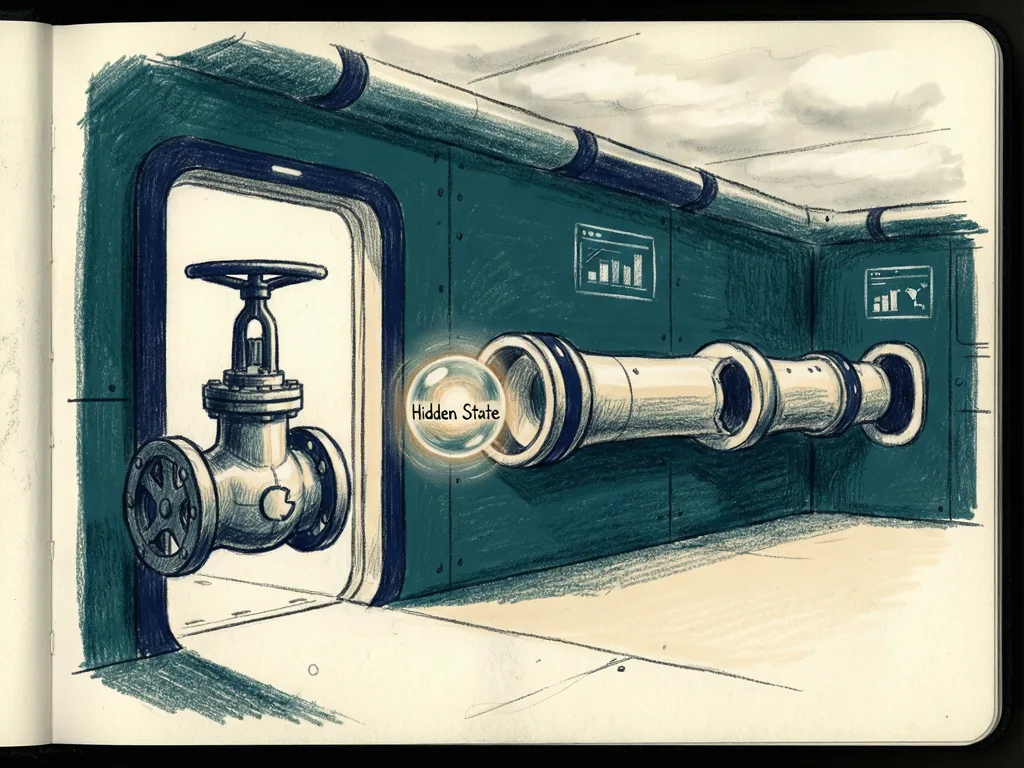
Unlike swapping in a smaller model, NESTONE keeps the backbone and final layers shared and adds reusable exits. Resolved decisions use less compute; harder decisions continue.
What the Seven Benchmarks Show
Across seven decision benchmarks, NESTONE matches or outperforms independently trained models at every depth, keeping each depth’s accuracy while improving accuracy-efficiency trade-offs because computation stops when the gate says it is unnecessary.
This supports the view that decision information is not evenly spread: early layers build essential features and intermediate layers carry much signal, so running all layers wastes compute; removing the final six layers without loss shows some depth is not required.
For LLM decision systems, consider each input’s needed depth, not only a smaller model. NESTONE shows one model can carry multiple decision paths, using shared computation and a lightweight gate to decide when to stop, maintaining or improving accuracy while making depth a tunable resource, not a fixed cost.
Comments (0)